本来就干净
Neural Networks
Are Already Clean
For years, experts said the inside of an AI was a tangle.
One of them looked again. It was a tidy city all along.
多年来,专家说 AI 的内部是一团乱麻。
其中一位又看了一眼:它一直是一座整齐的城。
A plain-language guide for people who don’t work in AI. If you do, go straight to the original:
这是写给不做 AI 的人看的通俗导读。如果你是业内人士,请直接读原文:
Neural Networks Are Already Clean ↗Nick Cammarata · Goodfire · 15 Oct 2026 · with the full data and interactive figures · 原文,附完整数据与互动图
Nobody writes the rules inside an AI model. It learns them from examples, and the result is billions of numbers no one designed. So what is actually going on in there?
AI 模型里的规则不是人写的,是它从例子里自己学来的,结果是几十亿个没人设计过的数字。那里面到底在发生什么?
For about a decade, the expert answer was discouraging: it’s a tangle, and you can’t read any of it until you untangle all of it. Nick Cammarata helped build that view. He co-wrote Zoom In (2020), one of the papers that made a famous “cat and car” neuron the textbook example of the tangle. Now, in a long essay for the AI lab Goodfire, he argues the tangle was mostly a misreading.
差不多十年来,专家的回答都让人泄气:里面是一团乱麻,不把整团解开,哪一部分都读不懂。Nick Cammarata 正是建立这个看法的人之一。他是 2020 年论文 Zoom In 的作者之一,正是这类论文让一个著名的“猫与汽车”神经元成了乱麻的教科书例子。现在,他在 AI 实验室 Goodfire 发表长文,说那团乱麻多半是看错了。
The news site AI/TLDR condensed the essay into six short paragraphs. This page takes them one at a time: what the paragraph says, what the essay means by it in plain words, and something to play with. First, three ideas you’ll need.
新闻网站 AI/TLDR 把长文浓缩成六个短段落。这一页逐段来读:这一段说了什么,原文用大白话讲是什么意思,再配一个可以动手玩的图。先讲三个你需要知道的概念。
An AI model is built from millions of tiny dials called neurons. Each one turns up for some things it sees and down for others. Nobody sets them; they settle into place during training.
AI 模型由几百万个叫神经元的小旋钮组成。每个旋钮看到某些东西会调高,看到另一些会调低。没人去拧它们,它们是在训练中自己定下来的。
If we could say what each neuron does, we could check what a model is really doing, not just what it says: whether it’s being honest, say. That project is called interpretability.
如果能说清每个神经元在做什么,我们就能检查模型实际在做什么,而不只是听它说了什么,比如它是不是在说实话。这件事叫可解释性研究。
Many neurons seemed to mix unrelated things: one for cats and cars. The leading theory, packing, said a model has more ideas than neurons, so it crams several into each. If so, you can’t read neurons one at a time. You first need special untangling tools.
很多神经元好像混着不相干的东西:一个神经元既管猫又管汽车。主流理论叫打包:模型要记的概念比神经元多,只好往每个神经元里塞好几个。真是这样的话,神经元就没法一个一个地读,得先用专门的分解工具把它们拆开。
Meet a neuron认识一个神经元
Show it a picture · 给它看一张图A real neuron from the small image model in ¶4, drawn as a dial; the needle positions are illustrative. · 这是第四段里那个小图像模型中的一个真实神经元,画成了旋钮;指针位置为示意。
- Neuron · 神经元
- One dial inside the model. Its “up” side and “down” side each respond to something.模型里的一个旋钮,“调高”和“调低”两侧各对某种东西有反应。
- Mixed-up neuron · 混杂神经元
- One that seems to respond to unrelated things. Researchers say polysemantic.好像对不相干的东西都有反应的神经元,术语叫“多义”。
- Packing · 打包
- The theory that models cram unrelated ideas into shared neurons. Researchers say superposition.认为模型把不相干的概念塞进同一个神经元的理论,术语叫“叠加”。
- Untangling tool · 分解工具
- A second AI trained to pull packed ideas apart. Usually a sparse autoencoder (SAE).专门训练来把打包的概念拆开的第二个 AI,通常是“稀疏自编码器”(SAE)。
- Offshoot · 分支
- A related side-job a neuron grows while it learns. The essay says recursive generalization.神经元在学习中长出的相关副业,原文叫“递归泛化”。
- Parameters · 参数
- The adjustable numbers a model is made of. More parameters, bigger model.组成模型的可调数字,参数越多,模型越大。
Nine in ten neurons have one job.
十个神经元里,九个只干一件事。
The headline claim: AI models are already mostly readable. In a first check of a large open-source language model (Qwen3-32B), about 90 in 100 neurons do one main job, and only 2 to 4 in 100 are still a mystery.
核心论点:AI 模型本来就大体读得懂。在对一个大型开源语言模型(Qwen3-32B)的第一次普查里,每 100 个神经元约有 90 个只做一项主要工作,还没搞懂的只有 2 到 4 个。
That number is startling if you know where the field was. In 2023, a major study by the AI company Anthropic looked at the neurons of a tiny model and found the typical one made no sense at all: its raters couldn’t even guess what it did. An automated project at OpenAI the same year, which Cammarata started, could explain only about 2 in 100 neurons, even by its most generous measure.
如果你知道这个领域原来在哪儿,这个数字就很惊人。2023 年,AI 公司 Anthropic 的一项重要研究查看一个小模型的神经元,发现典型的神经元完全说不通:评审连它是干什么的都猜不出来。同一年,Cammarata 在 OpenAI 发起的一个自动化项目,就算按最宽松的标准,每 100 个神经元也只能解释约 2 个。
Three years later, with better tools and a modern model, the picture flipped. Most neurons do one main job, often with a small related side-job. About 7 in 100 have two related jobs, like the same idiom in two languages. So far the pattern holds even in models with trillions of parameters. (Strictly, the essay counts each side of a neuron separately: what turns it up, and what turns it down.)
三年后,用更好的工具看一个现代模型,局面反过来了:大多数神经元只做一项主要工作,常带一点相关的小副业;每 100 个里约有 7 个有两项相关的工作,比如两种语言里的同一个习语。到目前为止,就连上万亿参数的模型也是这样。(严格说,原文把神经元的两侧分开计数:让它调高的东西,和让它调低的东西。)
Cammarata warns against holding the exact number tightly. It moves with where you draw the lines: how faint a signal still counts, and whether two closely related things count as one job. In the examples he looked at most closely, counting only strong signals, it was closer to 97 in 100.
Cammarata 提醒,别把这个数字抓得太紧。线画在哪里,它就跟着变:多弱的信号还算数,两件很相近的事算不算一项工作。在他看得最仔细的例子里,只算强信号,接近每 100 个里 97 个。
A census of 100 neurons一百个神经元的普查
Tap a ringed square to meet a real neuron from the essay. The two years look at different models with different methods, so this shows how much researchers could see, not one model getting tidier. Proportions from the essay; the grid is illustrative. · 点带圈的方块,认识原文里的一个真实神经元。两个年份看的模型和方法都不同,所以它反映的是研究者能看清多少,不是同一个模型变整齐了。比例出自原文,方格为示意。
The mess was mostly misreading.
乱,多半是看错了。
The twist: most neurons that looked mixed-up were simply misread, and models are tidier than the packing theory said.
转折在这里:大多数看起来混杂的神经元只是被看错了,模型比“打包”理论说的要整齐。
Packing was a bold idea. When a model has more to remember than it has neurons, the theory said, it starts cramming unrelated ideas into the same neuron, betting they’ll rarely come up at the same moment. If that’s true, what shares a neuron tells you nothing, and before you can study the model you have to train a second AI, an untangling tool, to pull the ideas apart.
“打包”是个大胆的想法。按这个理论,模型要记的东西比神经元多时,就会把不相干的概念塞进同一个神经元,赌它们很少同时出现。真是这样的话,哪些东西共用一个神经元就说明不了什么;想研究模型,得先训练第二个 AI,也就是分解工具,把这些概念拆开。
The ordinary way models learn predicts the opposite. Things end up sharing a neuron because they really have something in common worth noticing. The essay’s example: a neuron for floppy-eared dogs makes sense; a neuron for floppy-eared dogs and Latin poetry is what packing would allow. You can tell which is happening by watching a neuron develop during training.
模型平常的学习方式,预测的恰好相反:东西会共用一个神经元,是因为它们真有值得注意的共同点。原文的例子是:一个管“耷拉耳朵的狗”的神经元说得通;一个管“耷拉耳朵的狗和拉丁诗歌”的神经元,才是打包会允许的。要知道是哪一种,只要看着一个神经元在训练中长出来就行。
So when a neuron looks mixed-up, there are five suspects: our tools are too weak, our explanation is wrong, the model learned badly, the neuron grew a related offshoot, or, last, real packing. Calling a neuron mixed-up, the essay says, “is often more a claim about the observer than the neuron.” Cammarata used to blame packing first. Now he puts it last: it’s the hardest to test, and its only symptom, “this doesn’t make sense,” is exactly what weak tools look like too.
所以,一个神经元看起来混杂时,有五个嫌疑人:工具太弱、解释错了、模型学得不好、神经元长出了相关的分支,最后才是真的打包。原文说,说一个神经元混杂,“往往更多是在说观察者,而不是神经元”。Cammarata 以前总是先怪打包,现在他把它排在最后:它最难检验,而它唯一的症状“说不通”,恰好也是工具太弱时的样子。
Five suspects, eight cases五个嫌疑人,八份案卷
Pick a case to see what the neuron looked like and what it turned out to be. Cases from the essay, filed under the suspect that solved them. Packing has none: the essay knows of no confirmed case in a real model since one in 2019, and that one turned out to be a mistake. · 选一份案卷,看这个神经元当初像什么、后来发现是什么。案例出自原文,归到破案的那个嫌疑人下面。打包一栏是空的:据原文所知,自 2019 年那一例之后,还没有人在真实模型里确认过打包,而那一例后来也被证明是看错了。
None of this proves packing never happens, and the essay names the opposite risk: insisting every neuron must have a tidy story. Its answer is that the other four suspects can each be checked. A better tool either explains the neuron or it doesn’t; retraining shows whether learning was the problem; offshoots can be watched as they grow. And real explanations make sharp predictions. If you think a neuron is about Colorado, turn it up and see whether the model starts planning a hike.
这些都不能证明打包从不发生,原文也点出了反方向的风险:硬要每个神经元都有一个整齐的故事。它的回答是,另外四个嫌疑人都可以检验:换个更好的工具,神经元要么解释通了,要么没有;重新训练一次,就知道是不是学得不好;分支可以在训练中看着它长。而且真正的解释会做出很具体的预测。如果你觉得一个神经元和科罗拉多有关,就把它调高,看模型是不是开始计划去徒步。
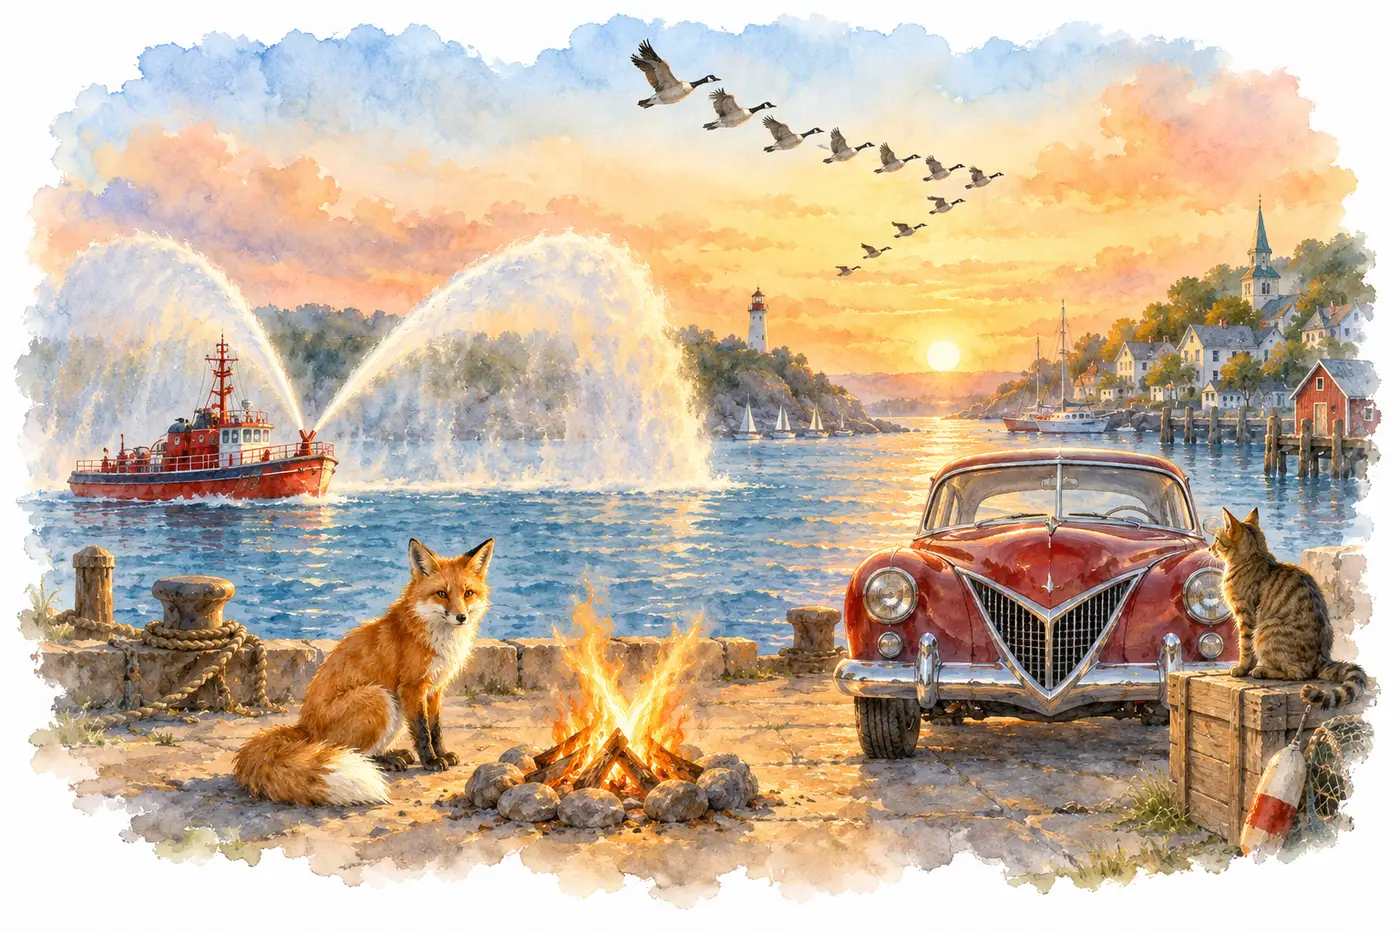
The cat-and-car neuron was a V.
猫与汽车神经元,其实是个 V。
What is it? An informal essay arguing that the textbook examples of mixed-up neurons, like the famous “cat and car” neuron in an image-recognition model, were misread. The mixing came from neurons growing related offshoots as they learned, plus weak tools and too little data.
这是什么?一篇非正式的长文,认为混杂神经元的经典例子,比如一个图像识别模型里著名的“猫与汽车”神经元,都被看错了。看起来的混杂,来自神经元在学习中长出的相关分支,再加上工具太弱、数据太少。
For years, one neuron in an image-recognition model from 2014 (InceptionV1; the neuron is called 4e:55) was the field’s favorite exhibit. It lit up for cat faces and for the fronts of cars, which seem to have nothing in common. In Zoom In, Cammarata and his co-authors wrote that it “isn’t responding to some commonality of cars and cat faces.” After months of looking at tidy neurons, he reopened the grid of images he’d seen hundreds of times and, for the first time, asked what one thing it might be. The answer came almost instantly: a V.
多年来,2014 年一个图像识别模型(InceptionV1)里的一个神经元(编号 4e:55),是这个领域最爱拿出来的展品。它对猫脸和车头都有反应,而这两样东西看起来毫无共同点。在 Zoom In 里,Cammarata 和合作者写道,它“并不是在响应汽车和猫脸的某种共同点”。看了几个月整齐的神经元之后,他重新打开那张看过几百遍的图,第一次问:它会不会其实只是一件事?答案几乎马上就出来了:一个 V。
The wiring agrees. The things that feed this neuron most strongly are V-shaped flames, the V-shaped spray of fireboats, the pointed faces of foxes. What turns it down is an O: round where the V is pointed. “Why would an arbitrary mixture of cats and cars need to connect so strongly to a flame?” The cat whiskers in the old pictures of what it “wanted to see” were a side effect of how those pictures were made.
线路也这么说。给这个神经元输入最强的,是 V 形的火焰、消防船喷出的 V 形水柱、狐狸尖尖的脸;让它调低的是一个 O:V 是尖的,O 是圆的。“一个猫和汽车的任意混合,凭什么要和火焰连得这么紧?”旧图里那些显示它“想看到什么”的猫胡须,只是那种作图方法的副作用。
The lesson travels. We describe neurons as lists of nouns (cats, cars), but many work more like verbs: they draw a distinction, pointed against round, that later parts of the model can use. Cammarata’s trick is to describe a neuron without listing any nouns at all. The shared pattern usually pops out, and it’s easy to test. If this is a V detector, it should also like bullet trains and the triangle rack on a pool table.
这个教训可以推广。我们习惯把神经元说成一串名词(猫、汽车),可很多神经元更像动词:它们做出一个区分,尖对圆,让模型后面的部分拿去用。Cammarata 的办法是:描述一个神经元时,一个名词都不许列。共同的模式通常马上就跳出来,也很好检验:如果它真是 V 检测器,它也该喜欢新干线列车,还有台球桌上的三角架。
Nouns, or a pattern?名词,还是模式?
Bars to the right turn the neuron up; bars to the left turn it down. Lengths are illustrative. Flames, fireboat spray and fox faces are its strongest inputs in the essay; bullet trains and pool racks are the essay’s suggested tests. · 向右的柱子让神经元调高,向左的让它调低,长短为示意。火焰、消防船水柱和狐狸脸是原文里它最强的输入;新干线和台球三角架是原文建议的检验。
What about neurons that really do seem to do two or three things? Most of them, the essay argues, grew that way. As a neuron learns, it branches out the way a tree branch sprouts twigs. Each step makes sense up close, even when the two ends look unrelated. One neuron in a language model started on the letters “iy” (as in “Miyazaki”), spread to “diy,” then to “do it yourself,” which has no “iy” in it at all.
那些真的好像同时做两三件事的神经元呢?原文认为,它们大多是长成这样的。神经元在学习时会分叉,就像树枝长出小枝;每一步近看都说得通,哪怕两端看起来毫无关系。语言模型里有个神经元,起初响应字母“iy”(比如“Miyazaki”里的),后来扩展到“diy”,再到“do it yourself”,而后者里根本没有“iy”。
You can watch it happen. In a retrained image model, one neuron began with yellow flowers, in photos that sometimes had a dog in them. Then it grew toward each thing in those photos: other plants and scenery, green things like balls, and dogs with no flowers at all. Seen only at the end, it looks like a random mix. Seen growing, every step is obvious.
这个过程可以亲眼看到。在一个重新训练的图像模型里,有个神经元一开始响应黄色的花,照片里有时还有一条狗。然后它朝照片里的每样东西生长:别的植物和风景、球这样的绿色东西,还有根本没有花的狗。只看结果,像是随便乱混;看着它长,每一步都很明白。
Every offshoot grows from something it resembles. That’s why what shares a neuron is a clue to how the model thinks, not noise.
每一根分支都从和它相像的东西上长出来。所以哪些东西共用一个神经元,是理解模型怎么想的线索,不是噪声。
Watch a neuron grow看一个神经元长大
Press Grow, or drag the slider. Then tick “If packing” to see what the packing theory would predict instead. Branch labels come from the essay’s examples; the packing items are made up. · 按“生长”,或拖动滑块;再勾选“若是打包”,看打包理论会预测什么。分支标签取自原文例子;打包那几项是虚构的。
Less room makes neurons broader, not jumbled.
空间少了,神经元变粗,不会打结。
How does he test it? He re-examines the classic examples, retrains image models across a 300-fold range of sizes, checks the neurons of a large language model, and squeezes one layer of an image model from 480 neurons down to 10. An untangling tool run on the squeezed layer finds no hidden extras packed inside, which he takes as evidence against packing.
他怎么检验?他重新审视经典例子,在 300 倍的尺寸范围内重新训练图像模型,普查一个大型语言模型的神经元,并把一个图像模型的一层从 480 个神经元压到 10 个。在压缩后的这一层上跑分解工具,也找不到塞在里面的额外概念;他认为这是反对“打包”的证据。
Start with the old exhibit. The last layer of that 2014 image model was the main evidence that models were nearly unreadable: about 5 in 100 of its neurons made sense with that era’s tools, by Cammarata’s memory, and another researcher put it at about none. Fix the tools and the very same model reads at about 50%. Retrain the same design with modern training habits: about 70%. Build a modern design of the same size and train it on the same photos: about 99%.
先看那件老展品。2014 年那个图像模型的最后一层,是“模型几乎读不懂”的主要证据:按 Cammarata 的记忆,用那个年代的工具,每 100 个神经元约有 5 个说得通;另一位研究者认为基本为零。把工具修好,同一个模型就有约 50% 读得懂。用现代的训练习惯把同一个设计重新训练一遍:约 70%。换一个同样大小的现代设计,用同样的照片训练:约 99%。
Same layer, four microscopes同一层,四台显微镜
Tap a step · 点一级Percentages from the essay (the first step is “about 5%” in Cammarata’s memory, “essentially none” in another estimate). The ten specimens are drawn, not real neurons. · 百分比出自原文(第一级是 Cammarata 记忆中的“约 5%”,另一位研究者估计“基本为零”)。十个样本是画的,不是真实的神经元。
Nothing about packing changed in those four steps; the tools and the training did. Next, size. If packing were the rule, the smallest model should be the most jumbled, since it has the least room. He trained three versions of the modern design, from 92 thousand to 28.6 million parameters, about 300 times apart. The small model’s neurons weren’t jumbled, just broader. One covers cars, trains and carts, and turns down for boats, planes and an ox-cart on water: roughly “moves on land” against “doesn’t.” The big model tells taxis from ambulances, and broccoli from cauliflower. With less room, a model stops sorting sooner. It doesn’t start mixing unrelated things.
这四步里,跟打包有关的什么都没变,变的是工具和训练。再看大小。如果打包是常态,最小的模型空间最少,应该最乱。他把那个现代设计训练成三个版本,从 9.2 万到 2860 万参数,相差约 300 倍。小模型的神经元并不乱,只是更粗。有一个管汽车、火车和推车,看到船、飞机和水上牛车就调低:大致是“在陆地上走”对“不在陆地上走”。大模型则能分清出租车和救护车,西兰花和花菜。空间少了,模型只是更早停止细分,不会开始乱混不相干的东西。
Same photos, 300× apart同样的照片,相差 300 倍
Drag the slider. Each pill is one neuron from the model’s last layer: + is what turns it up, − is what turns it down. Small and large examples are from the essay; the medium row is an illustrative in-between. · 拖动滑块。每颗胶囊是模型最后一层的一个神经元:+ 是让它调高的东西,− 是让它调低的东西。小模型和大模型的例子出自原文;中等模型那一行是示意的中间状态。
Then pressure. An early layer of the 2014 model is famous for ten curve detectors, each spotting curves at one angle. Cut that layer from 480 neurons to 10, a 48-fold squeeze with no way around it, and retrain from scratch. Packing predicts each of the ten becomes a mash-up: a curve plus a spiral plus a spider web. Instead the neurons got broader but stayed clean: one neuron for “curves and loops” in place of ten curve detectors, two circle neurons in place of several. Even squeezed, the model still names the right one of 1,000 kinds of object 58% of the time.
再看压力。2014 年那个模型靠前的一层,以十个曲线检测器出名,每个负责一个角度的曲线。把这一层从 480 个神经元砍到 10 个,压缩 48 倍,而且没有路可以绕过它,再从头训练。打包的预测是:这十个神经元每个都会变成大杂烩,一条曲线加一个螺旋再加一张蛛网。实际上,神经元变粗了,但依然干净:一个“曲线与圈”神经元,取代原来的十个曲线检测器;两个圆形神经元,取代原来的好几种。即便压成这样,模型在 1000 类物体里仍有 58% 的时候能叫对名字。
Squeeze a layer 48×把一层压缩 48 倍
Drawn after the essay’s figures. Accuracy figures are the essay’s; the shapes in the unnamed cells are illustrative. · 依原文配图重绘。准确率是原文数字;没有标名的格子里的图形为示意。
Could the ten curves be hiding in some combination of the ten neurons? That is exactly what an untangling tool is built to find. Run on the squeezed layer, it found nothing of the sort: only broad, bunched-up shapes, “not ten curves.”
那十条曲线会不会藏在十个神经元的某种组合里?分解工具正是为了找这种东西而造的。在压缩层上一跑,什么也没找到,只有又宽又挤在一起的形状,“不是十条曲线”。
More broadly, Cammarata trained several untangling tools and searched, by hand and with AI helpers, for anything they found that the neurons didn’t already have. He came up empty. In the last layer, 88% of what the tool found was near-copies of single neurons, and deleting everything else didn’t hurt the model’s accuracy at all. The tools were still useful for one thing: answering “what’s in this picture?”, especially in the smallest model, whose neurons are broadest.
更广泛地说,Cammarata 训练了好几个分解工具,自己动手、也让 AI 助手帮忙,去找它们发现了、而神经元里没有的东西。一无所获。在最后一层,分解工具找到的东西有 88% 几乎就是单个神经元的复制品;把其余的全删掉,模型的准确率一点没降。这些工具还是有一个用处:回答“这张图里有什么”,在神经元最粗的小模型里最有用。
Just look at the neurons.
直接去看神经元。
Why does it matter? Much of today’s research assumes neurons are jumbled and must be untangled first, usually with sparse autoencoders. If Cammarata is right, researchers can study neurons directly. He calls it a working hypothesis; the technical paper is still to come.
为什么重要?现在很多研究默认神经元是乱的,必须先拆开,通常用稀疏自编码器。如果 Cammarata 是对的,研究者就可以直接研究神经元。他称之为工作假设,技术论文还没发表。
There are two ways to study a model. One is ordinary science, the way a biologist studies a cell: look at the neurons and how they connect, watch information flow through them, run experiments, now with AI helpers running thousands at once. The other starts from a guessed list of concepts the model ought to contain and builds ever more elaborate tools to extract them, often without checking back against the model itself. The field started with the first and retreated to the second, because the model seemed to be a knot.
研究模型有两种做法。一种是普通的科学,像生物学家研究细胞那样:看神经元和它们怎么连接,看信息怎么流过它们,做实验,现在还可以让 AI 助手一次做上千个。另一种从一份猜出来的概念清单出发,造出越来越复杂的工具去把它们提取出来,常常不再回头对照模型本身。这个领域从第一种起步,后来退到了第二种,因为模型看起来是一团乱麻。
The untangling tools can even mislead. Run on the layer with the V neuron, one split the V back into a “car” piece and a “cat” piece: “like reconstructing Brooklyn from seventy disconnected pieces of Tokyo,” in the essay’s words. Reading the model’s own neurons avoids that. Anthropic once used untangled pieces to trace how its Claude model works through a medical diagnosis. Cammarata’s team found the same reasoning in another model’s plain neurons, and its hub is just four neurons. Switch them off and the model starts asking about itching instead, as if it had moved on to its next guess.
分解工具甚至会误导人。在 V 神经元那一层上跑,有个工具又把 V 拆成了一个“汽车”碎片和一个“猫”碎片,用原文的话说,就像“用七十块互不相连的东京碎片,拼出一个布鲁克林”。直接读模型自己的神经元,就不会这样。Anthropic 曾用拆出来的碎片,追踪它的 Claude 模型怎样一步步做出医疗诊断。Cammarata 团队在另一个模型的普通神经元里找到了同样的推理,它的中枢只有四个神经元。把它们关掉,模型就改问瘙痒的事,好像换到了下一个猜测。
And understanding snowballs. The essay compares it to a jigsaw or a crossword: each piece you place makes its neighbors easier. At first you’re stuck, because one neuron can only be explained in terms of others you don’t understand yet. Once the map fills in, each new neuron arrives with clues, and whatever still won’t fit points straight at a broken tool. That is how his team found an odd “double negative” behavior in a common type of neuron that, as far as they know, nobody had noticed.
而且理解会滚雪球。原文把它比作拼图或填字游戏:每放好一块,旁边的就更容易。一开始你会卡住,因为一个神经元只能用其他你还不懂的神经元来解释。等地图填起来,每个新神经元都带着线索来,剩下怎么也放不进去的,正好指向某个坏掉的工具。他们团队就是这样,在一种常见的神经元里发现了一种奇怪的“双重否定”行为,据他们所知,此前没人注意到。
Understanding snowballs理解会滚雪球
Each tile is a neuron. Tap one to study it, or send in the helpers. A toy version of the essay’s jigsaw idea: a neuron is cheaper to understand the more of its neighbors you already know, and each one teaches you a little about patterns that recur everywhere. · 每一块是一个神经元。点一块去研究它,或者派出助手。这是原文拼图比喻的玩具版:一个神经元的邻居你懂得越多,弄懂它就越省力;每弄懂一个,也会多懂一点到处重复出现的模式。
Put together, the essay says, the argument has four steps:
原文说,整个论证合起来有四步:
- Models learn by one rule, finding real patterns, not two. So nothing blocks ordinary science on them.
- With modern models and tools, that science goes much better than most people expect.
- Understanding snowballs, so it gets easier as the map fills in.
- Highly speculative: this might be most of what we need, and reading AI models might be far easier than assumed, possibly soon.
- 模型只按一条规则学习,就是找真实的模式,而不是两条。所以没有什么挡着我们对它做普通的科学。
- 有了现代模型和工具,这门科学进展得比大多数人预想的好得多。
- 理解会滚雪球,地图填得越满,就越容易。
- 高度推测:这也许就是我们需要的大部分东西,读懂 AI 模型也许比想象的容易得多,甚至可能很快。
He links it to a famous lesson in AI research, Rich Sutton’s “bitter lesson”: simple methods at enormous scale beat clever ones. “Maybe there’s a bitter lesson for interpretability too: scaling ordinary investigation beats engineering a clever new decomposition.” In other words, lots of plain looking beats a clever untangling machine.
他把这和 AI 研究里一条著名的教训联系起来,即 Rich Sutton 的“苦涩的教训”:简单的方法放到巨大的规模上,总能胜过聪明的方法。“也许可解释性也有一个苦涩的教训:把普通的调查规模化,胜过设计一种聪明的新分解。”换句话说,大量朴素的观察,胜过一台精巧的拆解机器。
A mixed-up neuron is a lead.
一个混杂的神经元,是一条线索。
You investigate, and ordinary science sharpens the story over time. · 你去调查,普通的科学会慢慢把故事讲清楚。
A mixed-up neuron is a dead end.
一个混杂的神经元,就是死胡同。
You stop studying it, so the evidence that would prove you wrong never arrives. · 你不再研究它,能证明你错了的证据也就永远不会来。
The two mistakes don’t cost the same, and Cammarata says he made the costly one for years: “I spent most of a decade figuring out how to look at a model rather than looking at it.”
两种错误的代价不一样,而 Cammarata 说,他多年来犯的正是代价高的那一种:“我花了差不多十年,琢磨怎样去看一个模型,而不是去看它。”
Become another reader.
做网络的另一个读者。
Who is it for? AI/TLDR’s answer: interpretability researchers and machine-learning engineers.
写给谁?AI/TLDR 的回答是:可解释性研究者和机器学习工程师。
That’s the brief’s shortest paragraph, but the essay’s biggest idea is for anyone. Inside a model, each part’s output is read by later parts, which build on it. So the parts are already made to be read, by the model itself. The network is “almost a fractal of explanations.” A researcher doesn’t need to untangle it. They need to become another reader.
这是简报里最短的一段,但原文最大的想法是写给所有人的。在模型内部,每个部件的输出都会被后面的部件读取,并在此基础上继续搭建。所以这些部件本来就是做出来给人读的,读者就是模型自己。整个网络“几乎是一个解释的分形”。研究者不需要把它解开,只需要做它的另一个读者。
Size helps rather than hurts. In a small town, asking for the financial district barely makes sense; in New York, you can find it on a map in a minute. His AI helpers found neurons for dogs’ ears faster in the bigger models, where neurons for pale ears, wavy ears and ears seen from the side all feed one “floppy ears” neuron. “Bigger models learn narrower neurons that are easier to recognize.”
规模是帮忙,不是添乱。在小镇上问“金融区在哪”几乎没有意义;在纽约,一分钟就能在地图上找到。他的 AI 助手在更大的模型里更快找到了管狗耳朵的神经元:管浅色耳朵、波浪形耳朵、侧面耳朵的神经元,都汇入同一个“耷拉耳朵”神经元。“更大的模型学到的神经元更窄,也更容易认出来。”
Why should anyone outside the field care? Safety. A common fear is that an AI could deceive us, and that the deception would hide somewhere in the model we never managed to check. Cammarata’s fear is different. Deception has no reason to hide from the model’s own parts, because they need to read it to act on it. “My fear is that deception will be right there, in plain sight, and we won’t know how to read it.” That is what makes learning to read neurons urgent.
圈外人为什么要关心?因为安全。常见的担心是,AI 可能欺骗我们,而这种欺骗藏在模型里某个我们没能检查到的地方。Cammarata 的担心不一样:欺骗没有理由躲着模型自己的部件,因为它们得读到它才能照着做。“我担心的是,欺骗就摆在那里,明明白白,而我们不知道怎么读。”这正是学会读神经元之所以紧迫的原因。
For researchers, he lists advice for his younger self, mostly about trusting neurons more and old tools less. It ends: whenever a neuron looks mixed-up, look harder. “The noise that stands out usually points to an explanation you don’t have yet.”
对研究者,他列了几条想给年轻时的自己的建议,大意是多相信神经元,少相信老工具。最后一条是:每次看到一个神经元好像混杂,就再仔细看看。“突出的噪声,通常指向一个你还没有的解释。”
His guess is that today’s most advanced language models, the kind behind chatbots, are where image models were eight years ago: readable, but waiting on many small fixes. What’s new is the workforce. “We’ve always had the best laboratory in natural science”: every neuron can be inspected, every experiment rerun on an identical copy. Now AI models can run those experiments themselves, and he thinks they may do in months for language models what took humans most of a decade for image models.
他猜,今天最先进的语言模型,也就是聊天机器人背后的那种,正处在八年前图像模型的位置:读得懂,只是还等着许多小修小补。新的是人手。“我们一直拥有自然科学里最好的实验室”:每个神经元都能查看,每个实验都能在一模一样的副本上重做。现在 AI 模型自己就能做这些实验,他认为,人类在图像模型上花了近十年的事,它们在语言模型上也许几个月就能做完。
Go deeper: the original essay, Neural Networks Are Already Clean, has the full technical argument, interactive figures and a microscope for exploring one model yourself. Also: AI/TLDR’s brief and the Hacker News discussion.
想深入:原文 Neural Networks Are Already Clean 有完整的技术论证、互动图,还有一台可以自己浏览模型的“显微镜”。另见 AI/TLDR 的简报和 Hacker News 上的讨论。